Human in the loop is not a review queue
A person who reviews every AI translation after it is made is not an oversight system. A useful loop decides which ambiguity reaches whom, why it does, and what their answer changes.
A reviewer at the end of a pipeline is not a loop
The usual picture of human-in-the-loop translation is a straight line: a model produces a target string, a linguist approves it, and the string ships. It looks responsible because there is a person in the picture. It is also a queue, and the queue is usually where the system stops learning.
Send every segment to a reviewer and the machine has not removed a decision. It has only moved the decision to the end of the pipeline, where it arrives without the screen, the product intent or enough time to reconstruct either. The reviewer learns to approve familiar-looking text. The difficult cases still get guessed at. The next release generates the same questions again.
That arrangement has a human in it. It does not have a useful loop. A loop has an entry condition, a person with a defined authority, and an output that changes what the system does next. Remove any one of those and “human in the loop” is a polite name for manual cleanup.
This is not an argument for unattended localization. It is the opposite. Some translation decisions are genuinely about a fact that does not exist in a resource file. The answer is to send those decisions to the person who knows that fact, and to keep every decision a program can settle out of their inbox.
Three human jobs that should not share one name
The term covers three different jobs. They are often drawn with the same little person icon, which is how a team ends up hiring a translator to do product governance or asking a product manager to supply training data.
| Arrangement | Decision of the human | Changes in |
|---|---|---|
| Feedback during model development | Which output is better, safe or on-policy | Training or evaluation data |
| Decision at run time | Whether this particular output may act or ship | The current case |
| Oversight after deployment | Whether the system, its policy or its limits must change | The workflow itself |
Human preference data is useful precisely because people can compare two imperfect outcomes even where no simple reward function exists. The early work that helped establish the pattern asked raters to choose between short clips, then learned a reward predictor from those comparisons 1. That is a learning loop. It is not a person watching a production system, and it is not a sign-off on a customer-facing decision.
NIST makes the same separation in plainer operational terms: a human–AI configuration can range from fully autonomous to fully manual, and roles and responsibilities need to be defined rather than assumed 2. The important word is not human. It is role.
Route the missing fact, not the model's uncertainty
The tempting routing rule is model confidence: below a threshold, send the string to a person. Confidence is a useful signal. It is not the reason a person is needed. A model can be confidently wrong about a fact it was never given, and it can be uncertain about a routine phrase a terminology check would settle exactly.
The stronger question is: what fact decides this output, and where does that fact live? If it is in the message syntax, a parser should decide. If it is in the approved termbase, a deterministic check should decide. If it is in the screen’s meaning, a screenshot and the feature owner may be necessary. If it is in a legal commitment, the relevant legal owner has to decide it.
That rule turns a vague escalation into a request that someone can answer. It also stops a language reviewer being asked to infer product intent from a key named settings.save. A reviewer can evaluate Spanish. They cannot discover whether Save means write a file, preserve a preference, or confirm a discount if the product has not supplied the context.
What a good localization loop sends to a person
Localization makes the distinction unusually visible because one release contains all three kinds of work. A changed message can be linguistically ordinary, structurally invalid or semantically impossible to settle from the source alone. Treating them as one review category means applying human attention where a test would be better and a test where context is missing.
| Arrived | Decided by | Best next step |
|---|---|---|
| An ICU message with a broken brace or missing placeholder | The message grammar and source variables | Reject it automatically before it reaches a reviewer |
| An approved term rendered differently in a familiar screen | The termbase and the scope of its rule | Flag the conflict; let the terminology owner change the rule if needed |
| A short label with no screenshot or description | The action, object and UI state it names | Ask the feature owner for context, then ask the linguist to translate it |
| A new destructive, financial or regulated user journey | Product policy and the consequences of misunderstanding it | Route the relevant locale expert and accountable domain owner together |
The first row is the happy case. An ICU parser does not become tired, does not skim a diff and does not need to be persuaded that a missing placeholder matters. It should fail the build. We have written about why a translation can be perfectly fluent and still be broken software in the case for constrained localization.
The third row is the case that automation cannot repair by becoming more fluent. A strong model may make the right guess. A strong translator may make the right guess too. Neither answer was entailed by the input. The workflow needs a context request, not another pass through the same text.
A decision must change the next decision
Once a person has made a decision, the system needs to know what kind of decision it was. An accepted translation is not one thing. It may mean “this target is right for this screen” or “this is the preferred rendering of a product term everywhere” or “the source copy is too ambiguous to translate safely.” Those are three different outputs and they should land in three different places.
The first belongs to the current translation. The second belongs in a termbase, translation memory or a retrieval example that future work can reuse. The third belongs with the source author, accompanied by the context that was missing. A fourth outcome is possible too: the reviewer may uncover an issue in the routing policy itself, such as a category of payment strings that should never have been auto-published.
This is why approval alone is such a thin signal. It tells the system that a result passed, but not whether the next identical-looking result should pass for the same reason. Ask for a compact rationale that is usable by the next person: the screen, the audience, the term rule or the risk class. Do not ask for an essay. Ask for the fact that explains the decision.
A glossary is one place these decisions can accumulate, though it is not the whole feedback system. The useful question is not whether a term appeared in a glossary; it is whether the rule is specific enough to be enforced in the context where it applies. A glossary is not enough is the longer version of that problem.
A reviewer without context or authority is only a delay
A reviewer needs more than a target string and two buttons. Give them the source, the target, a screenshot or a declared feature context, applicable terminology, the reason the item was routed and a way to escalate it. More context is not decoration; it is the evidence that makes their judgement about this product rather than about a sentence in isolation.
They also need authority that matches the request. A language reviewer should be able to correct wording and propose a terminology exception. They should not be silently made responsible for approving a medical claim or a legal disclosure. Conversely, a product owner can settle what a control does but cannot substitute for a locale specialist on register, idiom or grammar. Two people may need to answer one item, in sequence, because they own different facts.
This protects the person as much as the system. NIST notes that human–AI combinations can amplify bias in some judgment tasks rather than improve the decision simply by adding a person2. A reviewer asked to rubber-stamp a high-volume stream, with no context and no power to stop the stream, is set up for exactly that failure. They are not providing oversight; they are absorbing liability for a process they cannot inspect.
Measure the mistakes that escaped, not the people who clicked approve
Review coverage is easy to count and almost useless on its own. A team can review one hundred percent of segments and still learn nothing, route the wrong cases and publish repeated mistakes. The measures that matter describe the loop’s choices and its escapes.
| Measure | Reveals |
|---|---|
| Escape rate by route | Which auto-published or reviewed items later proved wrong, and whether the router missed a risk class |
| Reason for escalation | Whether most human work is missing context, terminology conflict, visual fit or a policy decision |
| Reuse of recorded decisions | Whether accepted feedback prevents the same question returning in the next release |
| Backlog age by risk class | Whether a supposedly safe gate is actually delaying urgent content |
| Disagreement and reversals | Which rules are ambiguous, under-specified or assigned to the wrong owner |
A high disagreement rate is not automatically bad. On a subjective marketing line, it can mean the system is surfacing a real choice. On a regulated product term, it is an alarm: either the rule is unclear or the wrong people are being asked. The metric only becomes useful when it is paired with the kind of decision the person was meant to make.
Oversight is a responsibility, not a native speaker
Human oversight is sometimes used as if it were a universal legal requirement for any AI-assisted work. It is not. Article 14 of the EU AI Act concerns effective human oversight for high-risk AI systems; it does not turn an ordinary interface translation into a high-risk system by itself 3. The classification and the surrounding use case matter.
The broader principle is still useful. UNESCO’s recommendation says that AI systems should not displace ultimate human responsibility and accountability 4. In a localization workflow, that does not mean a person must press approve on every label. It means the organization must be able to say who owns the policy behind a consequential translation, who can override the system and what evidence they used.
A native speaker is not a compliance mechanism. Where a message makes a financial, medical, legal or safety claim, the accountable domain owner is part of the loop. The locale expert still has indispensable work: they make sure that the intended claim survives in the target language. But they cannot certify an intent they do not own.
The point of the loop is to let the train keep moving
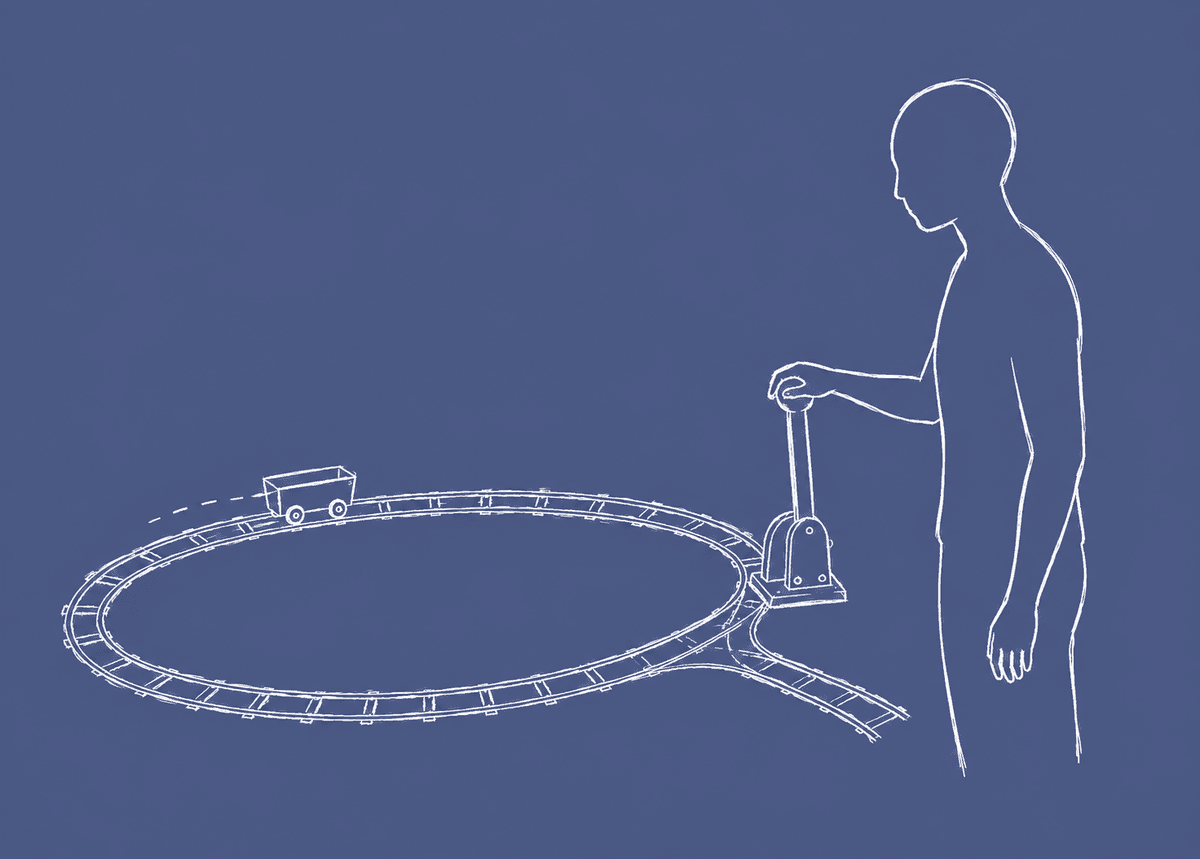
The good image for human-in-the-loop work is not a person standing in front of a conveyor belt, inspecting every box after the factory has finished. It is a railway switch. Most traffic follows a well-built track at speed. A defined condition sends the exceptional train onto a different track, where someone has the information and authority to set its direction.
Build the track first: validate structure, apply known terminology, preserve context and record provenance. Then define the switches: missing product intent, a new policy category, a high-consequence screen, a visual exception or an unresolved disagreement. Finally, make every human answer improve the route, the rule or the source material.
That is the loop. It does not slow automation down in the name of caution. It gives automation a reliable way to know when it has reached the edge of what it can decide.
References
- 1.Christiano et al., 2017 Deep Reinforcement Learning from Human Preferences arXiv:1706.03741
- 2.National Institute of Standards and Technology, 2023 Artificial Intelligence Risk Management Framework (AI RMF 1.0), Appendix C: AI Risk Management and Human-AI Interaction NIST AI 100-1
- 3.European Parliament and Council, 2024 Regulation (EU) 2024/1689 (Artificial Intelligence Act) Article 14, EUR-Lex
- 4.UNESCO, 2021 Recommendation on the Ethics of Artificial Intelligence UNESCO