Jev is type-safe. That does not make it right
TypeSafe's new decision model can return only valid choices. That removes malformed output, not misclassification; its multilingual promise now needs per-language evidence.
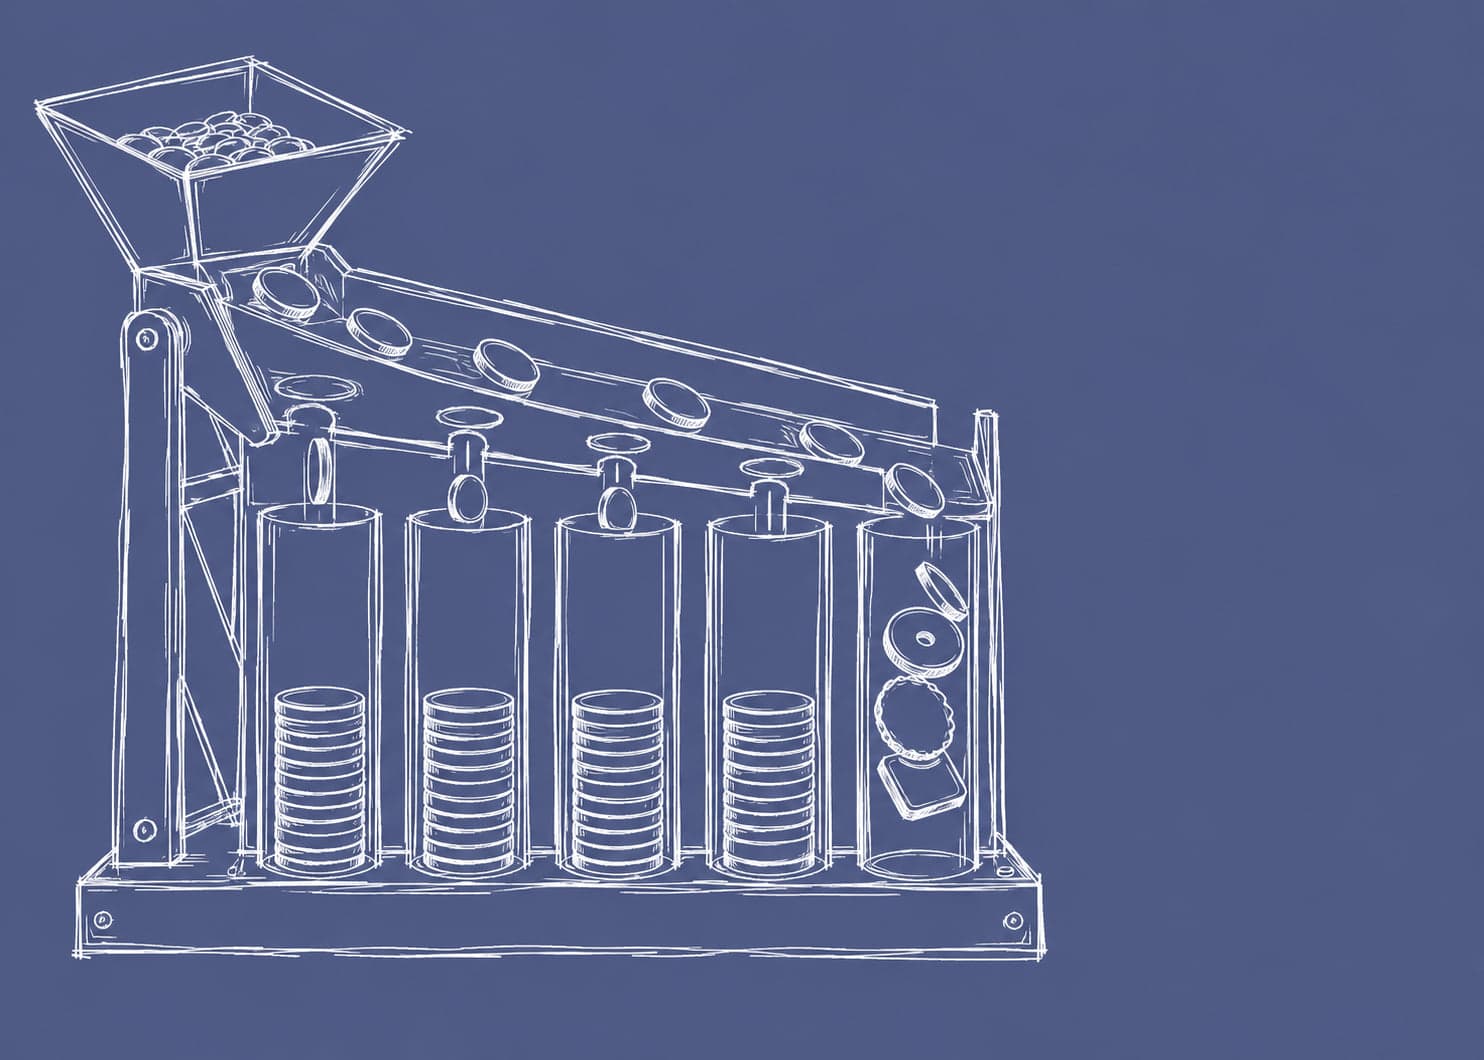
A classifier that never writes a sentence
Most language-model integrations ask for a small answer through a large opening. The application wants one department, one risk level or one yes-or-no decision. The model can still return a paragraph, a malformed object, an invented label or an apology.
Jev closes that opening. TypeSafe AI launched it as the first member of a new “System One” model family: state goes in, typed probabilistic decisions come out. It does not generate free-form text. Multiple questions can be evaluated against the same state in parallel 1.
The interface is genuinely useful. A Noul returns a probability for yes. A Choice selects from alternatives the application supplied and returns their probability distribution. A Score distributes probability across an ordered rubric2. The model behaves less like a reluctant author and more like a sorting mechanism.
That changes the contract between a model and ordinary software. It does not change the difference between a valid answer and a correct one.
Type safety closes one failure surface
Give a Choice three destinations named billing, technical and sales. Jev cannot return a fourth destination named Venus. It can still send a broken login to billing.
| Layer | Contract | Remaining failure |
|---|---|---|
| Output shape | The answer matches the selected primitive | The primitive may be wrong for the decision |
| Allowed values | A Choice stays inside the supplied alternatives | The wrong allowed alternative may win |
| Probability | The response carries a distribution | The distribution may not be calibrated for this population |
| Application action | Code can branch on a typed result | The branch may carry more risk than the evidence supports |
TypeSafe’s launch post calls schema matching guaranteed and describes Jev as unable to hallucinate. That is a claim about the space of representable outputs, not about classification accuracy1. The company’s own customer agreement draws the missing boundary: output may be inaccurate or erroneous, and the customer remains responsible for evaluating it 3.
This distinction is familiar in localization. A message can parse, preserve every placeholder and still choose the wrong word. Structure and semantics are different properties. Jev makes the structural property unusually strong at the model boundary. That makes the remaining semantic question easier to see, not safe to ignore.
The rubric moves into every request
A conventional task classifier usually binds its labels to a trained head. Jev moves much of that task definition into the request. The application sends the state, the question and the criteria for the available answers. TypeSafe says the same weights serve every account; customers adapt behavior through state, instructions, criteria and downstream code rather than per-customer fine-tuning4.
That is the interesting part of the product. A support system can ask for department, urgency and escalation in one call, then change the taxonomy without training another model. It is a programmable classifier whose program is partly natural language.
The last clause is also the cost. The rubric is now production logic. Rename an option, change a boundary case or translate the criteria, and you have changed the classifier even if the model version stays fixed. A deployment therefore needs two versions, not one: the model ID and the question contract. Logging only jev-1.13.0cannot reproduce a decision made under yesterday’s rubric.
Confidence is evidence, not policy
TypeSafe calls its post-training method Reinforcement Learning for Calibrated Decisions. Its stated target is group-level calibration: a set of outcomes assigned probability 0.8 should occur about 80% of the time. The documentation correctly warns that this says nothing certain about one answer 5.
That output is more useful than a naked label. It lets code abstain. But a confidence number does not decide what deserves automation. TypeSafe recommends different thresholds for different consequences and says the correct values depend on the domain and measured performance of the actual use case6.
A threshold is policy laid over evidence. Route a low-confidence ticket to a person and the consequence is waiting. Automatically reject a payment or suspend an account and the consequence is much larger. The same probability should not authorize both actions.
Nor should a threshold be copied between questions. TypeSafe documents cases where semantically related Noul andChoice formulations return probabilities that do not obey the identity a developer might expect7. Primitive, wording and rubric are part of the calibrated object.
Multilingual is an interface until each locale is measured
Jev accepts non-English input. That is an interface property. TypeSafe says English is the primary training language and currently produces the best accuracy; other languages, including CJK scripts, are handled but not equally well4.
The distinction matters because calibration can move even when the label set does not. A threshold chosen on English support tickets may admit more wrong answers in Japanese or Arabic. A translated rubric may move a category boundary. A locale-specific date or number may add a second error before classification even begins.
| Evidence | Breakdown | Deployment use |
|---|---|---|
| Accuracy and macro-F1 | Per locale and intent | Shows which labels and languages are being missed |
| Calibration | Per locale, rubric and model version | Sets an honest abstention threshold |
| Selective risk | At each proposed confidence gate | Shows the error left after uncertain cases are removed |
| Native production language | Separate from translated benchmark text | Tests expressions and boundaries that translation smooths away |
“Accepts Japanese” and “the Japanese threshold is safe” are not two strengths of the same claim. The second one requires observed outcomes from Japanese inputs.
The missing benchmark is the product question
TypeSafe publishes four workflow evaluations covering security incidents, agent traces, invoices and customer service. The harness decomposes each job into narrow model questions plus deterministic rules, then compares systems against consensus labels produced by other large models 8.
This evaluates Jev in the shape it was designed for. It is not an independent classification benchmark. TypeSafe says the workflows were written by its own model-capabilities team, acknowledges possible bias and describes its headline speed and cost gains as likely near the high end of real-world gains1.
The public launch page asks how Jev performs on public benchmarks and leaves the question unanswered. The reviewed model documentation publishes no standard accuracy, macro-F1 or per-language calibration table 1,4. So there is currently no defensible result called “Jev beats XLM-R” or “Jev replaces BERT.” The products expose different interfaces, and the missing Jev results do not become comparable because its API is attractive.
MASSIVE would be a useful first multilingual test. The dataset contains one million labelled virtual-assistant utterances across 51 languages and 60 intents, all within a single JevChoice’s documented 255-option limit2,9. More important than the headline average would be per-language accuracy, calibration and the error remaining after confidence-based abstention.
The jagged edges draw the boundary around the model
TypeSafe’s limitation page is unusually direct. Jev 1.13 does not count reliably. It advises keeping arithmetic and date comparison in code, filtering irrelevant state before the request, and testing adversarial content because state is not treated as hostile by default 7.
| Problem | Model role | Code role |
|---|---|---|
| Counting | Judge whether each item matches a semantic condition | Iterate and total the matches |
| Dates and amounts | Classify the meaning after normalization | Parse, normalize, compare and calculate |
| Long records | Judge the relevant subset | Retrieve and filter fields before the call |
| Structural identities | Answer one well-defined question | Enforce invariants across answers |
| Untrusted text | Classify under a precise rubric | Treat input as hostile and test injection paths |
Those limitations do not weaken Jev’s core idea. They describe it. A narrow probabilistic judgment surrounded by deterministic code is exactly where this interface is strongest. Trouble begins when the probability is mistaken for arithmetic, a security boundary or a database constraint.
Evaluate the sorter, not the label
Do not evaluate Jev by asking whether the demo label looks plausible. Evaluate the complete sorter: the state admitted, the rubric used, the alternatives available, the probability returned and the action taken afterward.
Freeze a model ID and a rubric version. Build a held-out set from the language and traffic the system will actually see. Record the full probability distribution, not only the winning label. Measure accuracy and calibration per locale. Then replay the proposed policy at several thresholds and price both kinds of mistake: the wrong automated action and the correct case sent to review.
Add the failure conditions TypeSafe already names: irrelevant context, conflicting criteria, injected instructions, numeric formats, dates and equivalent questions expressed through different primitives. Repeat the run when the model, rubric or supported locale changes.
Jev has moved an old boundary in a useful direction. The application no longer has to coax a classifier-shaped answer from a text generator and hope the JSON survives. What it receives is a typed decision with explicit uncertainty. That is a better component.
It is not a verdict. The machine in the illustration never drops a token outside its tubes. The unanswered question is whether each token fell into the right one.
References
- 1.Almeida, 2026 Introducing System One Models & Jev TypeSafe AI, 15 September 2026
- 2.TypeSafe AI API reference TypeSafe AI documentation
- 3.TypeSafe AI, 2026 Master customer agreement TypeSafe AI, updated 19 September 2026
- 4.TypeSafe AI Models TypeSafe AI documentation
- 5.TypeSafe AI AI primer TypeSafe AI documentation
- 6.TypeSafe AI Confidence TypeSafe AI documentation
- 7.TypeSafe AI, 2026 Jev 1.13 jaggedness TypeSafe AI documentation, reviewed 17 September 2026
- 8.TypeSafe AI Workflow evals TypeSafe AI evaluations
- 9.FitzGerald et al., 2022 MASSIVE: A 1M-Example Multilingual Natural Language Understanding Dataset with 51 Typologically-Diverse Languages arXiv:2204.08582